Vitron Unified Vision LLMs

Vitron: Unified Vision LLMs

A thread from pixel-level unification to cross-vision synergy

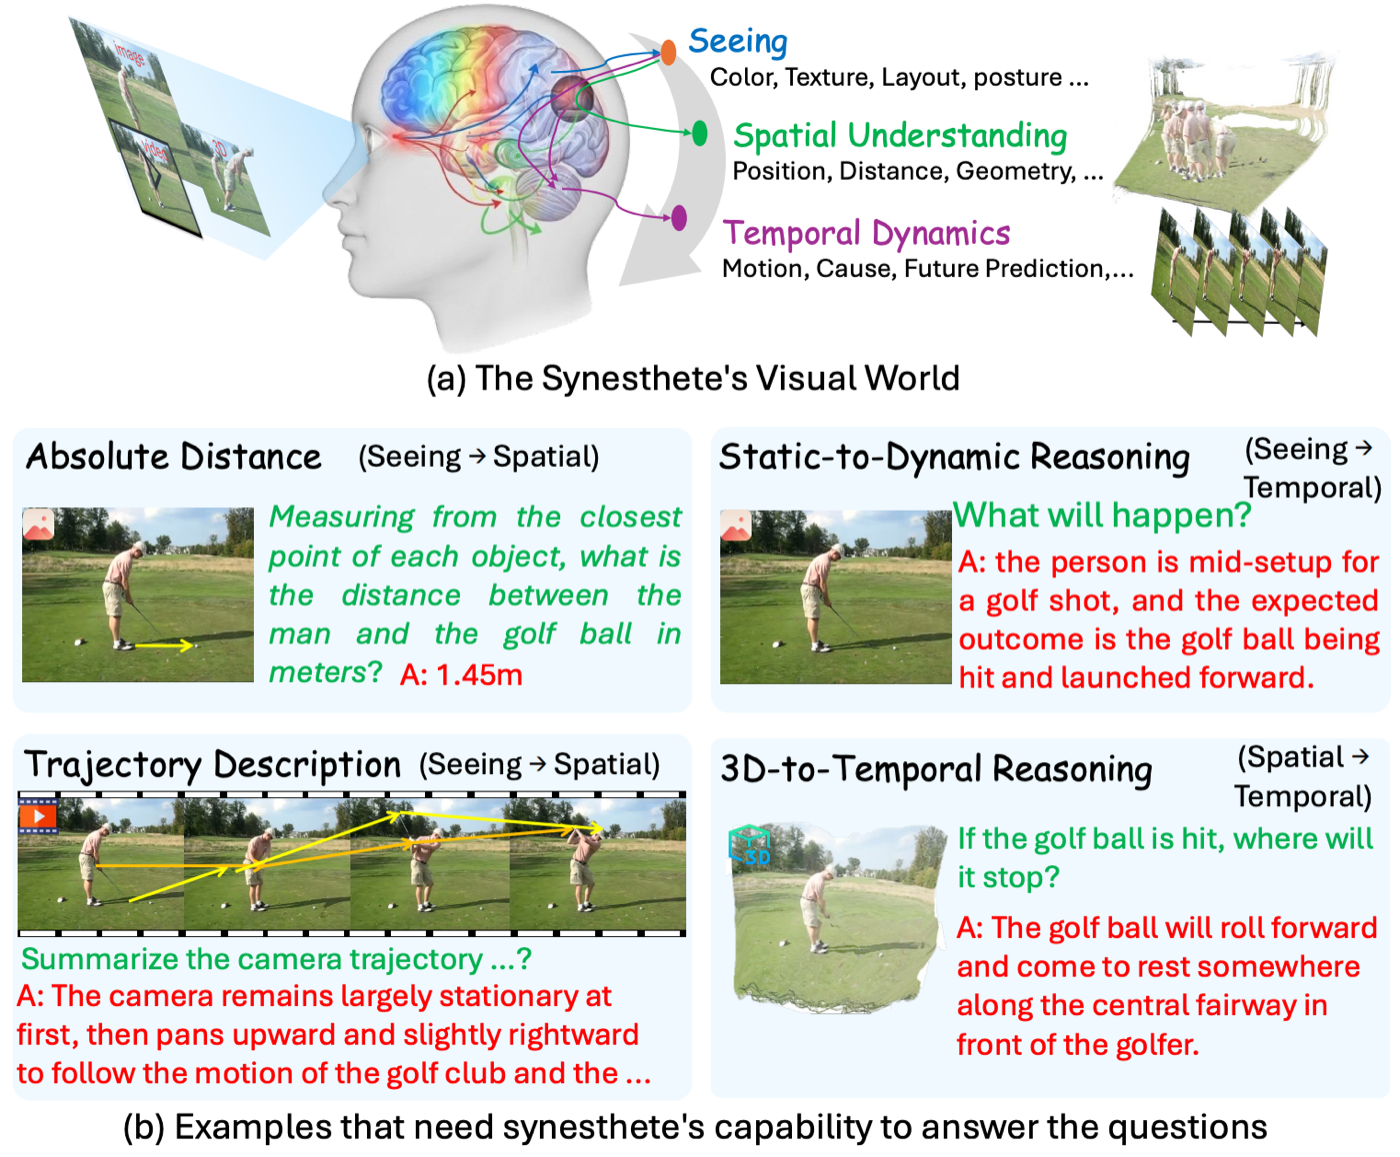
Unified large vision models need more than modality coverage. They need a shared visual reasoning surface. Vitron studies how a single large vision model can coordinate fine-grained perception, generation, editing, and cross-vision reasoning across images, videos, 3D, and richer pixel-level interfaces. The goal is not only to connect modalities, but to let them sharpen each other.

Concept illustration for Unified Vision LLMs

Research Papers

These works study a common question: how should large vision models unify visual functions and modalities without flattening away the specific priors that make each visual source useful?

2024 NeurIPS

Vitron: A Unified Pixel-level Vision LLM for Understanding, Generating, Segmenting, Editing

Vitron is a universal pixel-level vision LLM spanning static images and dynamic videos across four major vision task clusters. Vitron pushes toward a multimodal visual generalist by combining image, video, and regional encoders with backend specialists under an LLM backbone. It is designed to support visual comprehension, generation, segmentation, and editing in a single system, while preserving precise message passing between language reasoning and visual execution.

  • Hybrid instruction passing with discrete text and continuous signal embeddings.
  • Pixel-level spatiotemporal alignment for fine-grained visual capability.
  • Cross-task synergy learning across 12 tasks and 22 datasets.
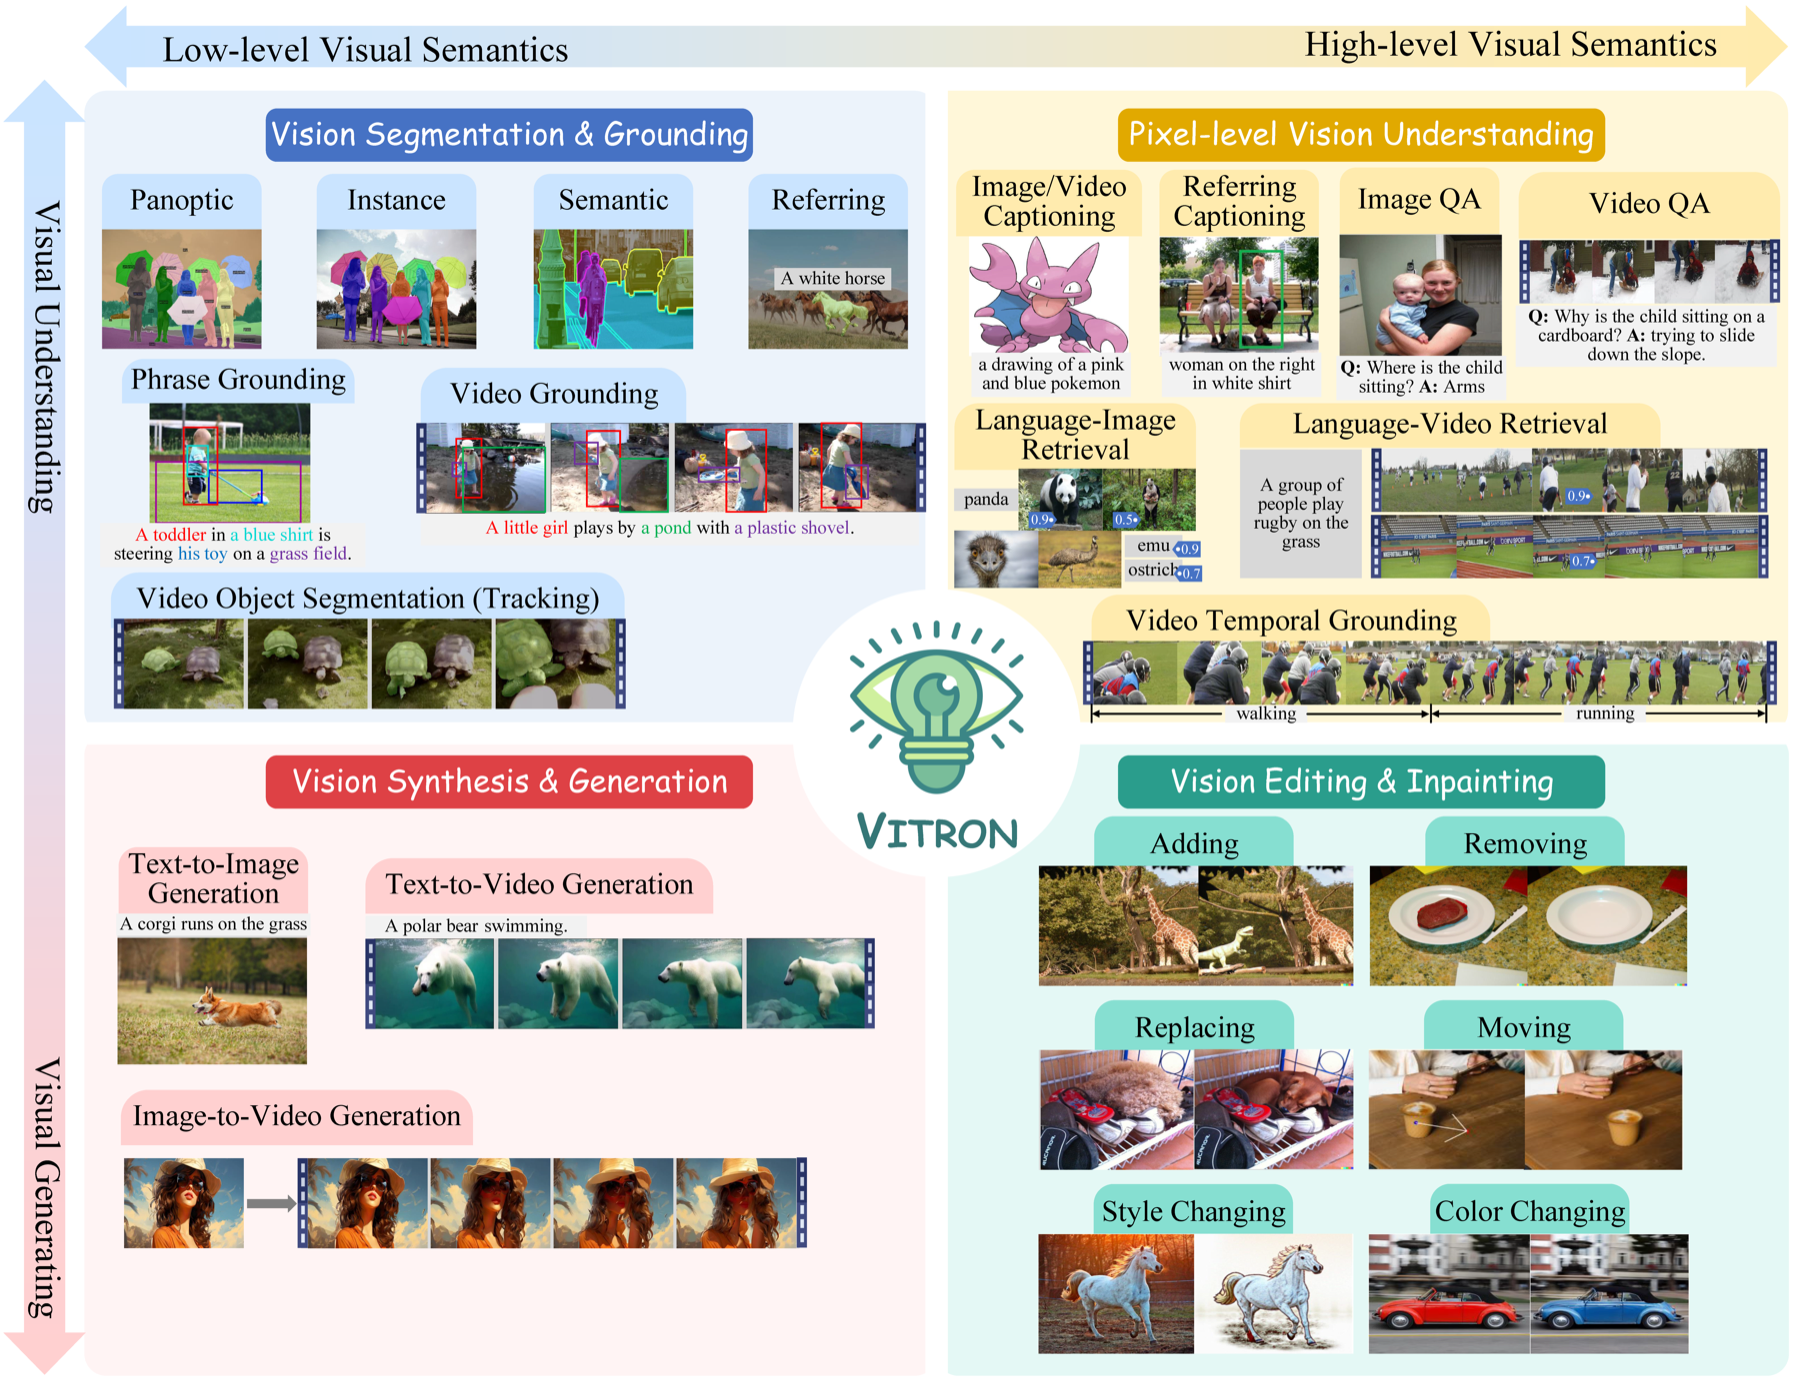
Overview figure for the VITRON paper
2026 CVPR

Poly-V: Modeling Cross-vision Synergy for Unified Large Vision Model

Poly-V is a unified large vision model that treats synergy across image, video, and 3D as a first-class modeling objective. Poly-V argues that true unification is not just functional integration. It builds a sparse Mixture-of-Experts large vision model with a dynamic modality router, then trains it with a synergy-aware paradigm so modality-specific priors can interact, refine one another, and support richer visual reasoning.

  • Sparse experts specialize in modality priors while remaining mutually connected.
  • Synergy-aware tuning combines distillation with object- and relation-level alignment.
  • Strong gains on 10 benchmarks spanning image, video, 3D, and synergy-heavy reasoning tasks.
Overview figure for the Poly-V paper
2026 Preprint

VitronEdit: Universal Visual Editing across Images, Videos, and 3D Scenes

VitronEdit is a universal framework for visual editing across images, videos, and 3D scenes within a single shared model. Because paired 3D editing data is scarce, VitronEdit treats static frames, temporal frames, and multiview observations as one sequence representation, transferring editing knowledge learned from abundant image and video data to 3D scenes, and further strengthens structural consistency with geometry-aware post-training.

  • Unified sequence representation for image, video, and multiview 3D editing.
  • Progressive multimodal training that transfers editing semantics from 2D to 3D.
  • Geometry-aware post-training with depth and camera-pose supervision for geometric consistency.
Teaser figure for the VitronEdit paper